
Dolphin Research

Dolphin Research

Thinking with soul, research with attitude

0Following5,255Followers1,958Likes & Bookmarks
Dolphin Research
Dolphin Research
D
Dolphin Research

AWS opts for simplicity: can modular, plug-and-play networking deliver?

In our recent networking series, Dolphin Research reviewed 2D fat-tree switched fabrics. These are exemplified by Nvidia and AMD, while Google represents 3D torus direct-connect topologies.

$NVIDIA(NVDA.US) sets the industry benchmark. It develops the full stack in-house across hardware, protocols, and software, with tight HW/SW co-design delivering best-in-class performance. Its road map iterates quickly and in large leaps, prompting rapid shifts in supply-chain dynamics.

$AMD(AMD.US) follows Nvidia but competes a generation behind. Helios largely copies the GB300 NVL72 networking architecture...

aws 2.
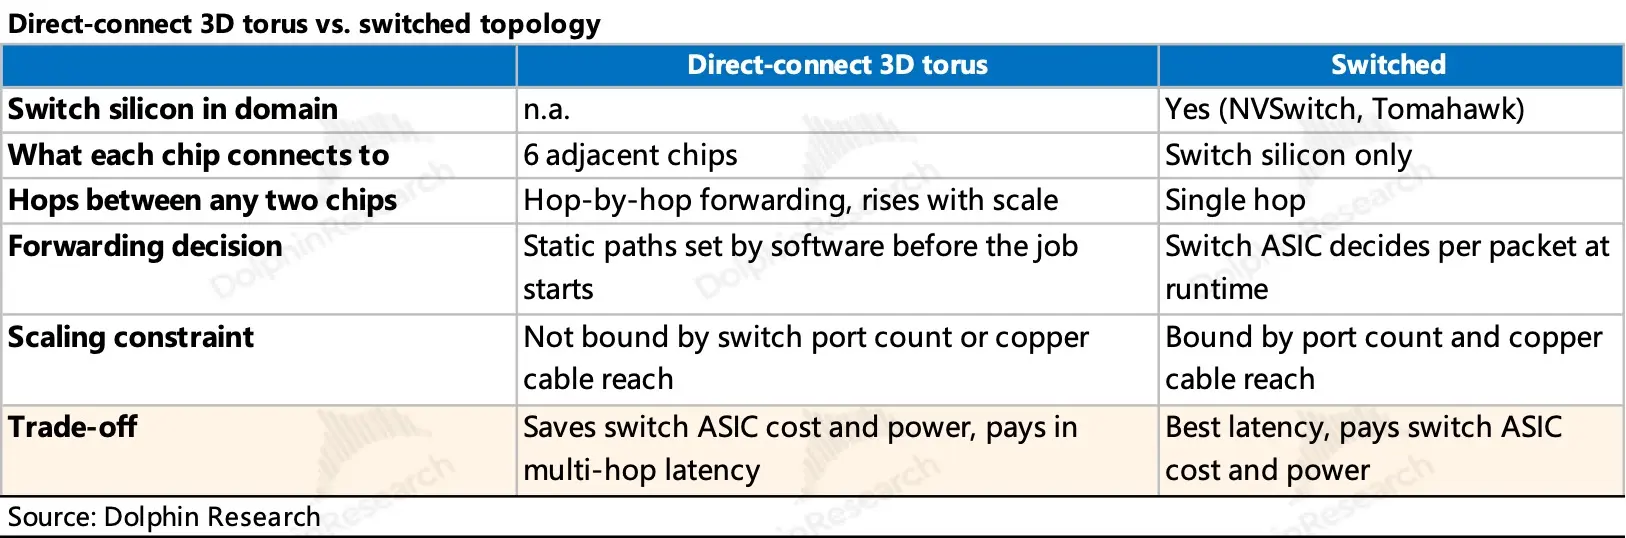
Direct-connect 3D torus vs. switched topology Direct-connect 3D torus Switched S
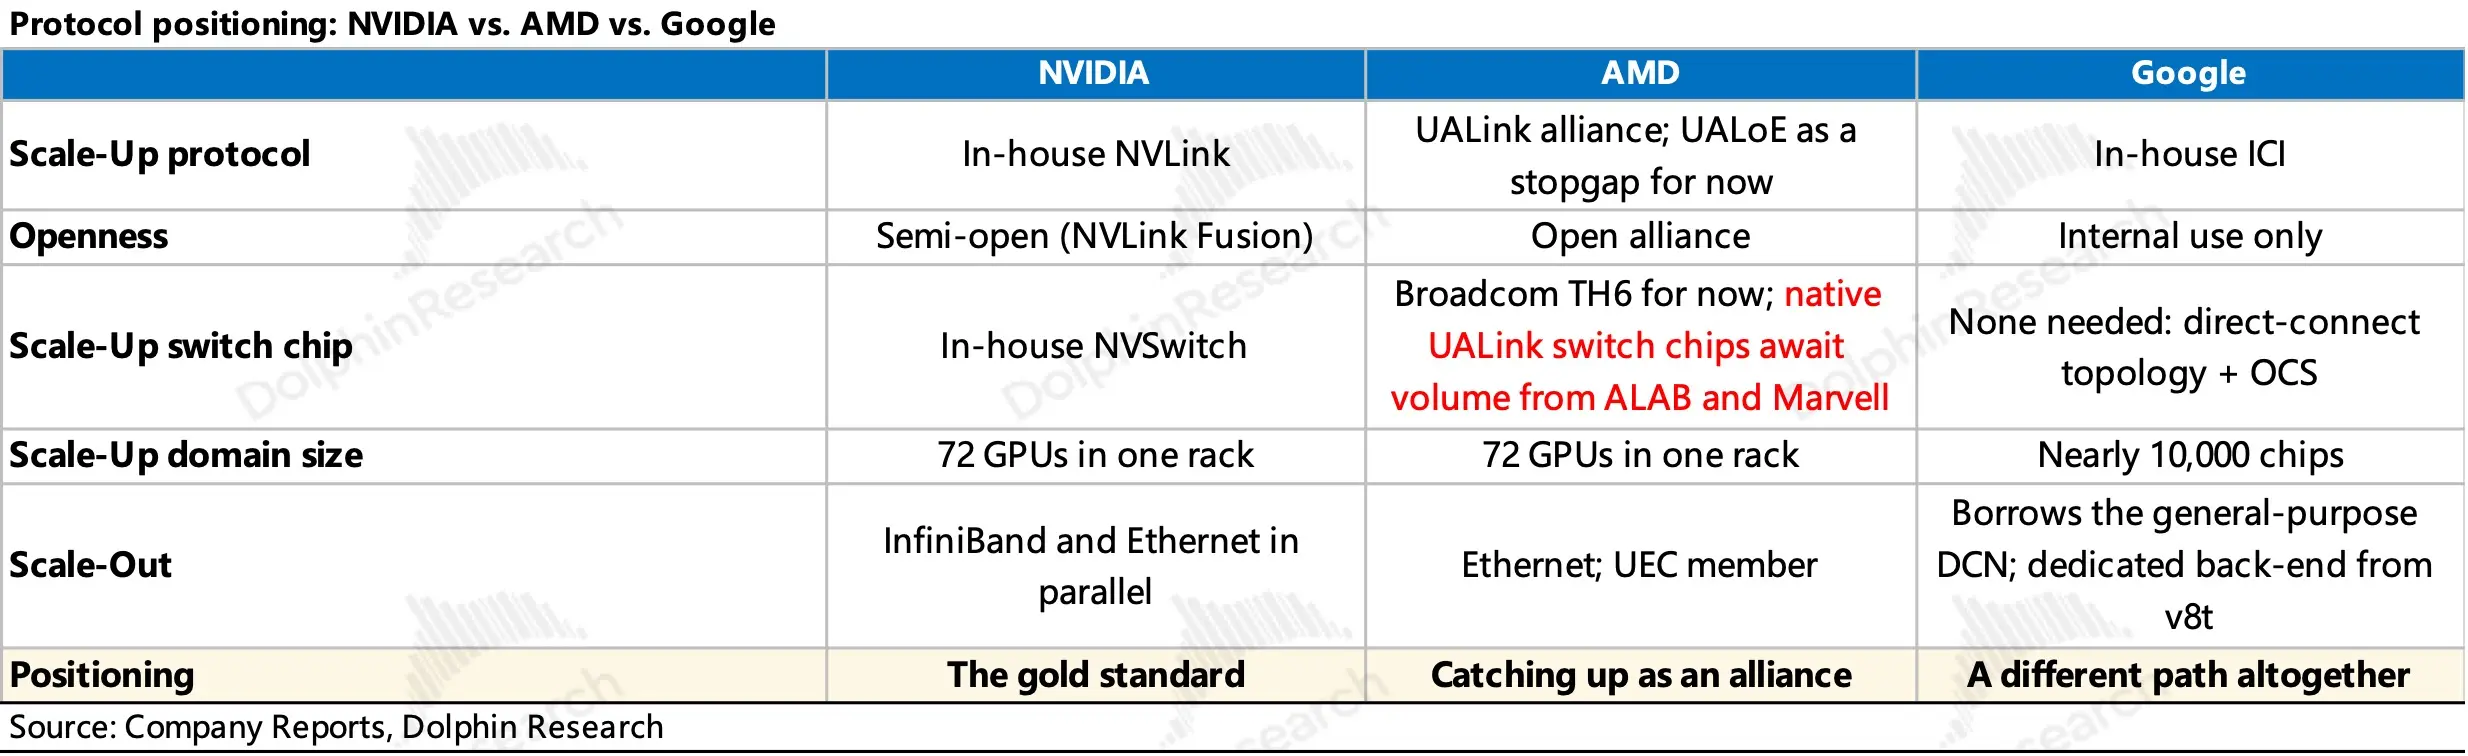
Protocol positioning: NVIDIA vs. AMD vs. Google NVIDIA AMD Google UALink allianc
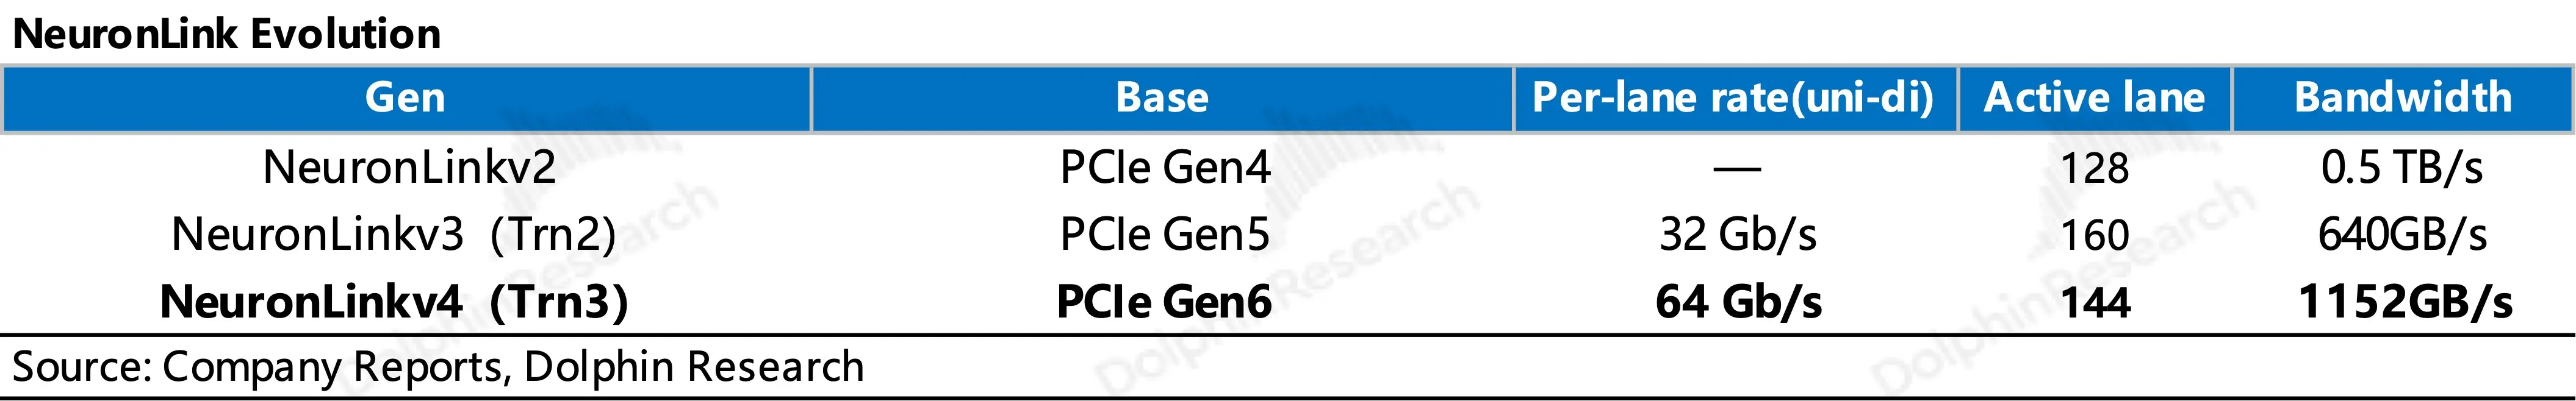
NeuronLink Evolution Gen Base Per-lane rate(uni-di) Activelane Bandwidth NeuronL+38
Deep ResearchAmazon
D
Dolphin Research

Cerebras: Wafer-scale 'monster' chip—can it challenge NVDA?

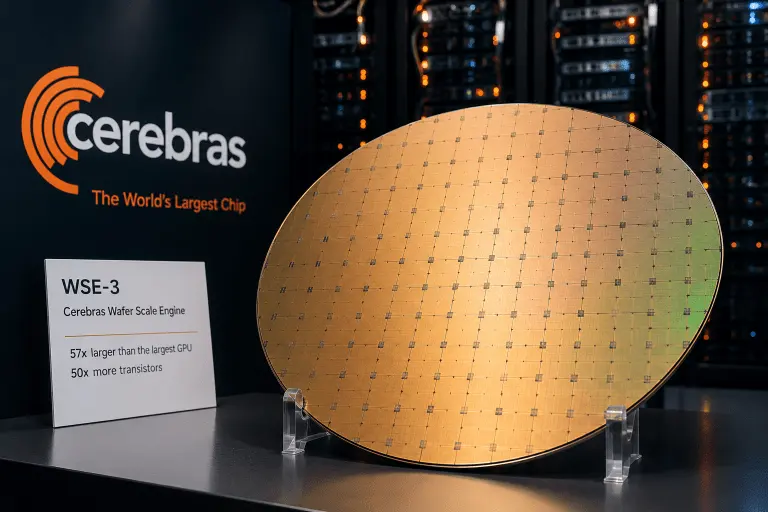
Most chip designers, including NVIDIA, lay out circuits on a large wafer, then dice it into smaller dies. Those dies are interconnected to build AI accelerators, improving yield by avoiding scrapping an entire wafer due to defects.

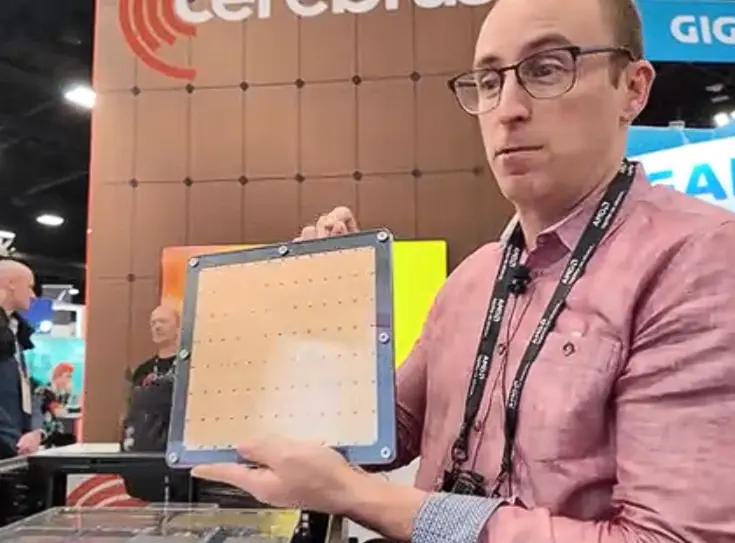
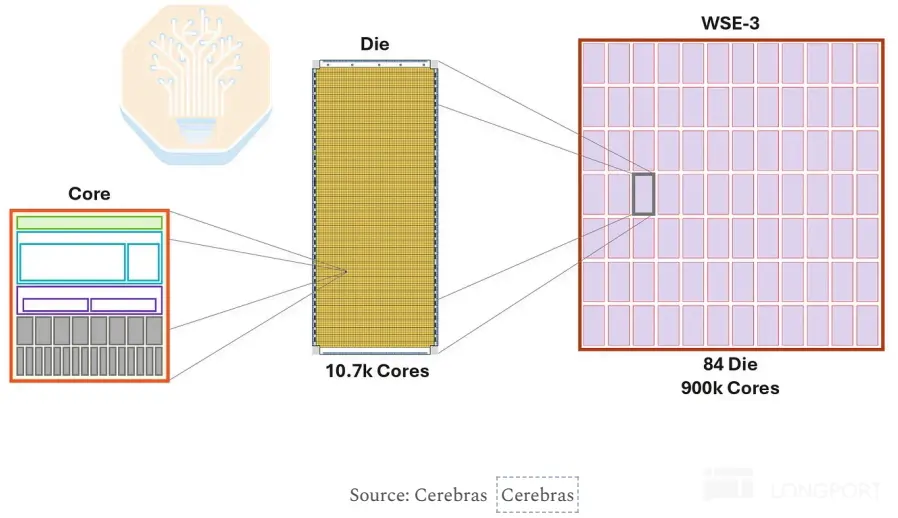
One company refuses to follow that path. It treats the whole wafer as a single chip—a 21.5 cm x 21.5 cm square roughly matching the largest rectangle you can cut from a 12-inch wafer—packing 4 trillion transistors and 900k cores; the company is Cerebras. The bottleneck for GPU inference is the 'memory wall'...

ESE EiiW18823 cerebras 5 The World's Largest Chip 日 H 舒 点 WSE-3 器 Cerebras Wafer
CIv GIG A
WSE-3 Die Core 10.7k Cores 84 Die 900k Cores Source: Cerebras: ICerebras ONGPORT
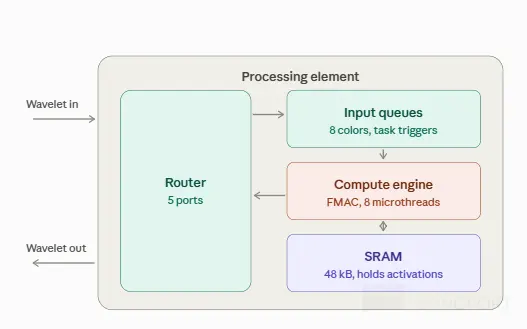
Processing element Waveletin Input queues 8colors, task triggers Router Compute +27
Deep ResearchCerebras
D
Dolphin Research

SK hynix: Can LTAs smooth the cycle? How far can valuation go?

HBM prices have surged, and SK hynix shares have jumped as much as 10x over the past six months, but Samsung Electronics and Micron Technology are rapidly grabbing supply-chain share.

In Part 1, we mapped the DRAM/HBM supply-demand gaps and identified the cycle inflection; please refer to that piece. However, an industry upcycle does not guarantee steady profits at the company level.

Here we stay focused on SK hynix, analyzing its partnerships with NVIDIA and major ASIC customers. We also compare long-term agreement strategies across the Big Three. We then model forward earnings and assess the current valuation, as incremental memory demand in the AI era is concentrating with a handful of XPU vendors and cloud players...

SANDISK 951 SandiskDr.
HBM demand breakdown 120% NVDA AMD & other GPUs ASIC (TPU, AWS,etc) 100% aRes e
HBM in market share within NVDA (sales) 120% NVDA: SK Hynix 100% Researc Resear
Figure 40: HBM wallet share within ASIC % 100% U70 U70 7% 10% 12% 90% 80% 70% 50+12
SK HynixDeep ResearchAppraisal value
D
Dolphin Research

OpenAI's 20bn revenue gap sparks uproar; real impact looks limited — a sentiment false alarm.

The bearish headline that OpenAI's ARR went from 70bn to 50bn triggered a global pullback in AI plays.

Dolphin Research offers a quick take on where expectations diverge.

1) The 70bn vs 50bn gap mostly reflects definitional differences rather than a real shortfall. Many leading model vendors periodically disclose ARR, but methodology matters — gross vs net revenue, annualizing a 28-day avg x12 vs a single recent week x52, etc.

Disclosure timing matters too, e.g., whether it follows a blockbuster flagship launch or a promotion; without that context, cross-company comparisons are not apples-to-apples.

1 SOpenAI SearchGPT ● Q What are you looking for?
How Anthropic Sells Claude: Who Runs Inference, Who Bills, How Revenue Is Booked
Where Each $100 of Revenue Goes: OpenAI vs Anthropic,Q3-2026 Run-rate (est.) vs
Anthropic Overtook OpenAI on ARR in Spring 2026, but OpenAI Is Growing Faster Ag+2
OpenAIAmazonMicrosoft
D
Dolphin Research

How the memory race ultimately ends comes down to one question: will AI be more constrained by capacity or by bandwidth?

That single variable drives three scenarios.

1) Capacity-bound: parameter counts stop exploding, and demand is driven by more users and longer context windows.

Back-end memory, standard DDR, and HBF can fill the gap.

Memory reverts to a commodity game focused on capacity and cost — but it is also the most 'cyclical', and once supply ramps, pricing comes under the most pressure.

2) Bandwidth-bound: parameter counts keep climbing and speed requirements rise.

The focus of competition shifts from 'stacking memory' to packaging and substrate/process technology, with bargaining power spilling over to foundries like TSMC.

Memory vendors start to look more like 'die suppliers'.

3) Both in short supply: the industry enters a memory 'super-cycle'.

All paths are pursued in parallel, DRAM wafer and advanced packaging capacity both run tight.

Memory makers carry the most weight in this setup.

In practice, all three will likely coexist; the difference is which one dominates.

Watch a few signals: the layer and stack counts of new HBM, realized speeds for HBM4E, the relative capacity ramp between CoWoS and DRAM wafers, and first-wave adoption of HBF.

图片 1,共 2 张
图片 2,共 2 张
D
Dolphin Research

$NVIDIA(NVDA.US) can raise memory capacity via two parallel paths: push process limits to make each stack denser, or avoid chasing per-stack density and win on unit count. While the industry races to stack HBM higher, Nvidia is taking the opposite route by cutting layer counts.

First, the stacking route. HBM co-packages with the GPU under a shared lid, so total Z-height is capped (HBM4 relaxes it to 775 µm). To squeeze in more layers, dies must be thinned further and micro-bumps shrunk, or switched to Cu-Cu bonding, which raises process complexity, lowers yield, and complicates thermals.

The upside is that each added layer benefits from first-rank bandwidth.

Nvidia, however, is moving the other way. For the next-gen Rubin Ultra, HBM was initially specced at 16 layers, then cut to 12, and is now rumored to drop to 8.

That would put per-stack capacity at roughly 192GB—below the current Rubin's 288GB—an unusual 'step back' for a flagship. These are not officially confirmed and only reflect options being weighed.

Why cut layers? Capacity is the core constraint: the most advanced HBM4E is more complex, and suppliers cannot ramp to Nvidia's desired volume and cadence in the near term. At equal capacity, HBM already consumes ~3–4x the wafers of commodity DRAM, and higher stacks burn even more materials.

More importantly, total system capacity can still go up via scale-up, linking more GPUs together. A B300 rack is around 20TB, and while Rubin Ultra's per-stack is smaller, interconnecting 576 GPUs can push system memory to ~110TB. In essence, cutting layers and shipping more stacks trades process difficulty and cost for volume under tight supply.

This approach creates two new bottlenecks: first, the constraint shifts from memory makers' expansions to base-die and co-packaging capacity, i.e., how much capacity it can secure from TSMC. Second, it raises the bar for GPU interconnect and memory pooling.

So whether to increase or decrease HBM layers hinges on two factors: whether bandwidth can keep up—stacking higher only helps if bandwidth scales—and whether packaging and base-die capacity is ample—if sufficient, cutting layers and using more stacks is viable.

图片 1,共 1 张
D
Dolphin Research

SK hynix: How Long Can the AI-led Memory Supercycle Last?

The last two pieces from Dolphin Research outlined the underlying logic and trajectory of the 'memory' rally from a tech lens, while this one shifts back to the company level. It zeroes in on the most representative HBM leader of this cycle — $SK Hynix(SKHY.US).

SK hynix’s current position is delicate. Memory prices have surged and HBM remains tight, driving a step-change in earnings.

The stock at one point rallied ~10x within six months.

On the other hand, Samsung and Micron are rapidly plugging into the supply chain of core customers such as Nvidia, shifting Hynix’s edge from exclusive to merely leading.

As a manufacturing company...

SKhynix N Nasdaq SKhynix SK hynix KRX 000660 Now Listed on Nasdaq 321,000 +1.000
DDR Demand -- Conventional DDR Demand Growth--Conventional bn Gb Computer (PC+La
Figure 3: DRAM/NAND as % of flagship smartphone Figure 4: DRAM/NAND as % of mid/
Products Shipment Growth DDR Used per Unit mn unit IohinResearch GB PC Laptop Mo+23
SK HynixDeep ResearchAppraisal value
D
Dolphin Research

On Oct. 7, Anthropic launched Claude Haiku 5.5. This is a Agent-focused lightweight model for repetitive micro-tasks such as retrieval, classification, and database queries. On the core Agent skill of Computer Use, the task completion rate surged from 16% to 72% vs. Haiku 4.5.

Beyond that, baseline capabilities in knowledge work and coding improved materially. On GDPval-AA, scores nearly doubled and are now close to Sonnet 5.5, Anthropic's mid-sized model.

Versus its closest peer GPT‑6 Luna, Haiku 5.5 leads on overall performance at a similar price point. In knowledge work (GDPval-AA), it is already approaching Sonnet, the mid-sized model in Anthropic's lineup.

The headline remains pricing: Haiku 5.5 cuts input/output token rates by 90% vs. the prior gen, driving a 75% drop in per-task costs. This aligns with the recent trend of aggressive price cuts among closed-source models in H2.

With GPT‑6 Luna first and now Haiku 5.5, the investment cases for Zhipu and MiniMax are being questioned, triggering sharp stock moves. MiniMax, which positions on value-for-money, plunged 12% today.

Let’s dig into Haiku's value-for-money. Key points below:

(1) Performance: broadly on par overall, with different strengths in the details. On composite intelligence, Haiku 5.5 roughly matches the 'Flash' versions of China’s leading models. In sub-use cases, Haiku excels at Agent coding (Terminal‑Bench 4.0) and HLE (Human Level Exams), but trails Chinese models on SaaS workflow automation.

(2) Pricing: Haiku adds real pressure. In the sub‑100k token per‑request tier (which Anthropic says covers ~90% of use cases; beyond that, pricing is 5x higher, erasing the value edge), unit token rates are lower across input, output, and cache write/read.Except for Mimo‑V2.6 Flash which is absolutely cheaper than Haiku, other China 'Flash' models are not cheaper, and MiMo Flash underperforms Haiku. On a per‑task cost basis, Haiku also offers strong value.

Haiku’s launch raises two debates:

1) Closed-source price cuts vs. rising compute costs? Key signals follow.

Dolphin Research believes base compute is indeed getting pricier. First, the following indicators stand out.

Ornn’s B200 rental index rose ~20% over the past 30 days. Agent workloads lift the CPU/GPU ratio, adding CPU cost; CPU vendors such as Intel are raising prices amid tight capacity. DRAM prices are still rising even as the second derivative slows (TrendForce expects Q4 DRAM contract prices to climb 10%–15% QoQ, and including HBM to 15%–20%).

However, lower prices from closed-source models are not purely about weak demand or worsening competition. Lightweight models and architecture optimizations improve GPU efficiency, so even as hourly GPU rents rise, hourly throughput climbs as well, cushioning margins while cutting price.

In addition, portfolio strategy matters. As the lightweight line in the Claude family, Haiku helps with user acquisition and boosts interaction frequency. Sacrificing some Haiku margin—or even taking losses—to replace user retention costs can make sense.

2) North America’s closed-source cuts vs. China’s open-source hikes? The contrast is notable.

Haiku 5.5’s strong value-for-money cannot be ignored for Chinese models. For the first time, a North American model beats most China peers of similar performance on value—for lightweight tasks. At the flagship tier, though, Haiku 5.5 does not change the fact that some Chinese models still hold a value edge.

China’s AI labs are currently prioritizing next‑gen flagships with far larger parameter counts. Leading players are targeting models above the 3T‑parameter level.

We believe the big‑parameter path is right for Chinese models: Scaling laws have not fully broken, and price wars alone are not sustainable. As OpenAI and Anthropic squeeze the share once won by lightweight, value‑oriented models via portfolio tactics, Chinese players must raise flagship competitiveness to retain users on overall cost advantages.

Inevitably, this pushes inference costs higher. Hence China’s end‑user price hikes are largely pass‑through rather than a sign of stronger product competitiveness, though relative value may still remain after the hike.

Valuation takeaways: Based on the last earnings call and recent checks. Updates as follows.

(1) $Z.AI(02513.HK) guides to YE2026 ARR of $3bn (raised from $2.4bn in mid‑Sep). Top‑tier institutions are at ~$3.3bn; after today’s 8% drop, market cap is ~$40bn, taking P/ARR down to 12x.

(2) $MINIMAX-W(00100.HK) still guides to YE2026 ARR of $1bn, unchanged from early‑year; the Street is generally at ~$1.2bn. After a 12% drop today, market cap is ~$9.5bn, putting P/ARR below 8x.

For comparison with the two North American leaders: multiples below. Context matters by stage and model mix.

Anthropic trades around 9x–20x P/ARR, based on ~0.97tn latest May financing valuation to nearly 2tn IPO valuation against ~100bn ARR. The range reflects scenario‑based ARR assumptions.

OpenAI officially guided 2024 revenue of 30bn; third‑party estimates put current ARR at 50bn–70bn, assuming 60bn–80bn by year‑end. With late‑Sep financing valuation of ~1.4tn, P/ARR is also around 20x.

On this view, Zhipu and MiniMax look meaningfully undervalued (even below other unlisted China model names such as Kimi and MiniMax in primary markets). Beyond structurally lower GPM vs. O&A (30% vs. 60%), Dolphin Research thinks the secondary market—especially HK—liquidity and trading conditions are a bigger swing factor.

Dolphin Research will keep tracking US‑China model progress. Near term, we will watch token share on OpenRouter (China has led since Jun): after Haiku 5.5 and Luna, will China’s share be overtaken in Oct–Nov? We will also revisit model economics post Anthropic’s Nov IPO.

图片 1,共 4 张
图片 2,共 4 张
图片 3,共 4 张
图片 4,共 4 张
D
Dolphin Research

Overseas LLM price war hits China AI names; NVDA RTX Spark opens pre-orders | Daily News Recap

1008 | Dolphin Research Focus: 🐬 Macro/Industry 1) HK-listed LLM names weakened across the board today. The overseas LLM space kicked off a new round of price cuts.

Anthropic launched next-gen Haiku 5.5 and lowered inference costs, while OpenAI introduced lower-priced GPT-6 Sol and Luna, with Luna API pricing 50% below the prior GPT-5.6 series. The market worries that as frontier models keep improving and API prices fall rapidly...

图片 1,共 1 张
Today’s Key News Recap
D
Dolphin Research

$Taiwan Semiconductor(TSM.US) TSMC does not produce a single DRAM chip, yet it is becoming central to high‑performance HBM. From HBM4 onward, two critical steps — a customized base layer and co‑packaging of memory with the GPU — run through TSMC's lines.

Entry 1: the base layer. It serves as the bottom‑stack 'relay station' in HBM. HBM3e and earlier used simpler 20nm flows that DRAM vendors could make in‑house; with HBM4, nodes move to 12nm and flagships to 2/3nm, forcing outsourced fab to TSMC (Samsung can self‑manufacture).

The bar is higher because a doubled bus width raises PHY precision requirements, and functions like the memory controller that lived in the XPU are migrating to the base layer. As the base layer shifts from off‑the‑shelf to customer‑specific parts — e.g., NVDA's NVHBM uses a proprietary protocol claiming +30% bandwidth and −15% power — reliance on TSMC's advanced nodes deepens.

Entry 2: CoWoS packaging. HBM's high bandwidth depends on co‑packaging with the XPU on a silicon interposer, primarily via TSMC's CoWoS, where CoWoS‑L is already mainstream with a >60% share.

Capacity cadence matters more: DRAM wafers will not meaningfully free up until 2027 (+15%~20%), while CoWoS capacity in 2027 doubles vs. 2026 — packaging is expanding faster than DRAM bits.

The bottleneck and value are shifting toward packaging and foundry. How much HBM a DRAM vendor can deliver now depends not only on its own lines, but also on how much base‑layer wafer capacity and CoWoS slots it can lock at TSMC.

Take SK hynix's HBM4: it only handles die fabrication and stacking, while the base layer is co‑designed with NVDA and manufactured by TSMC, and final packaging is also completed at TSMC. If the industry moves toward 'fewer layers, more dies', it saves DRAM wafers but consumes more packaging capacity.

The choke point shifts further from 'DRAM vendor expansion' to 'TSMC ramp'.

图片 1,共 2 张
图片 2,共 2 张
D
Dolphin Research

$SK Hynix(SKHY.US) Stacking over a dozen memory dies and then bonding them, SK hynix can finish the job in one shot. Samsung and Micron have to press and bond layer by layer.

Its proprietary bonding process is one of SK hynix's key competitive edges.

SK hynix uses MR-MUF: align all layers once, complete bonding in a single pass, then fill gaps with resin. Samsung and Micron use TC-NCF, bonding each layer through repeated heat and pressure.

The toolsets are fundamentally different.

Two gaps stand out. One-shot bonding reduces steps, boosting efficiency and yield, while layer-by-layer bonding means one defect can scrap the entire stack.

Repeated thermal compression also warps and cracks ultra-thin wafers more easily, pushing yields even lower.

This flows straight to GPM, giving SK hynix a structural edge.

So why don't Samsung and Micron just copy it?

First, SK hynix has locked up the process and key liquid resin materials with patents. Second, Samsung and Micron have sunk heavy capex into the TC route, making a pivot costly.

So they are effectively skipping this generation and betting on next-gen 'hybrid bonding' to leapfrog.

A bonding process itself is a ready-made moat. Bonding technology will be a hidden line separating winners from laggards among memory makers going forward.

Samsung and Micron appear more inclined to develop next-gen hybrid bonding directly to attempt a leap. $SKHY 2X Short ETF(SKDD.US) $T-REX 2X Long SKHY Daily Target ETF(HYNX.US) $SKHY 2X Long ETF(SKHX.US)

D
Dolphin Research

HBM is pricey and supply-constrained. The memory 'dies' themselves are not fundamentally different from standard DDR; the real divergence is in architecture and packaging, distilled into two ideas:

First, 'stacking.' There are two ways to expand capacity: increase bit density per die, or pack more dies into the same footprint. The first path has hit a wall—DRAM scaling is hard, as shrinking cells too far lets electrons leak across boundaries, corrupting data; the most advanced nodes are only 11–12nm, and even by 2030 may reach just ~10nm, far from logic at 2–3nm.

More importantly, logic follows Moore's Law, roughly doubling density every ~2 years, while memory does not enjoy that tailwind. Since density gains from process shrinks are limited, the industry chose the second route—stacking dies vertically to increase capacity.

HBM4 already stacks 12 layers, triple the first generation. Market chatter suggests it could reach 16 layers around 2026–27.

Second, 'attaching.' To deliver bandwidth, HBM must sit next to the GPU and be co-packaged on the same silicon interposer. Consumer GPUs place DRAM chips around the core on the PCB, but server GPUs must cram HBM into the same small area as the core, and that area cannot simply be enlarged.

Space is even tighter because the four edges around the core are reserved first for I/O and external interfaces. What is left for memory is mainly the top and bottom edges, with the left and right already taken, so when you run out of horizontal room, the only way is to build upwards.

In short, 'stacking' brings capacity, and 'attaching' brings bandwidth. The technical barriers and high cost of HBM are the price paid for these two choices.

图片 1,共 1 张
D
Dolphin Research

Alibaba shared a preliminary preview for next quarter with the market this morning. Overall looks solid: cloud is tracking higher on growth and margin as expected, and e-comm is still bottoming but not deteriorating further.

Details follow. Highlights are below.

1) Cloud: Sep Q revenue expected to grow >50% vs. +45% in Jun Q. External revenue growth is running ahead of overall, broadly in line with prior expectations.

Margin is the standout. EBITA margin is seen around ~15% vs. 12% last quarter, slightly ahead of the expected pace and moving quickly toward the 20% long-term target.

2) E-comm: Sep Q CMR expected to decline mid-single-digit % YoY vs. -7.5% in Jun Q. Excluding definition/scope changes, roughly +1%, broadly similar to last quarter. At least no worse.

Domestic e-comm EBITA expected roughly flat YoY, vs. ~3–4% decline last quarter. This also suggests a bottoming-and-recovery trend, with platform subsidies trimmed.

3) Food delivery: Sep Q loss approx. RMB 9 bn, slightly narrower than RMB 10 bn last quarter. A neutral print.

4) New AI Lab (model R&D and Qianwen consumer and enterprise businesses): Sep Q loss expected at RMB 10–11 bn, a modest improvement vs. last quarter. Also neutral.

5) No equity financing in FY27; other alternatives will be considered. In other words, no direct share dilution.

$Alibaba(BABA.US)

D
Dolphin Research

MRVL (Trans): Data center capex to exceed RMB 3 tn; the company has secured 5-year capacity.

Below is the meeting Trans of MRVL 2026 Investor Day (covering FY27), compiled by Dolphin Research. For in-depth analysis, cf. 'Marvell: Long-term guidance surges — confidence or just painting a rosy picture?'

I. Core highlights. 1) Shareholder returns & capital allocation: From FY21–FY26, the co. invested approx. $8 bn in organic R&D and about $11 bn in M&A.

It also returned about $4 bn to shareholders via dividends and buybacks. Looking ahead, with structurally stronger cash flow...

图片 1,共 1 张
MarvellConference Minutes
D
Dolphin Research

On Oct 2 and Oct 6, SpaceX rallied 7.4% and 7.6% in single sessions.It broke through $155 and $170, rebounding nearly 60% from the Aug low.

Dolphin Research view:

This is the post-Q2 playbook: SpaceX, like Tesla, is priced off event catalysts rather than near-term earnings delivery.Long-dated bets such as space compute and a 10GW AI build-out drive most of the valuation but contribute little profit today, so the stock is essentially a probability-weighted option whose catalysts raise exercise odds.Over the past two weeks, catalysts across multiple legs landed almost simultaneously.

1. Starship: On Sep 28, the 14th flight reached orbit for the first time — approx. 275km orbit, all 26 Starlink V3 satellites deployed and linked.Although one vacuum Raptor shut down early and the mission shortened to ~3 hours from six orbits, the full loop of 'orbit + payload deployment + controlled re-entry' has been proven end to end.In the same week, three historic missions were completed within 24 hours (NASA crewed Crew-13, Google AI chip payload to orbit, Starship Flight 14).

Google's TPU prototype satellites (Project Suncatcher, 4 TPUs) entered orbit for testing on Oct 1 via Falcon 9 Transporter-18.That said, true validation of the $200/kg economics still hinges on full reuse — simultaneous capture of both stages.

Musk has guided that Flight 15 (expected late Oct–early Nov) will attempt the first upper-stage capture using the launch tower's mechanical arms.This is the single largest positive catalyst since the IPO.

2. AI: Five clients' compute ARR has reached ~$54.5bn.Disclosed annualized compute contracts total approx. $41.0bn: Anthropic pays $1.25bn/month, Google pays $920mn/month starting in Oct, a new agreement from Dec 1 pays $1.11bn/month (~$13.3bn annualized), and Reflection totals ~$6.3bn over three years.Anthropic's F-1 indicates its agreement cap with SpaceX could be as high as $84.5bn.

3. Musk Beta: Tesla Q3 deliveries were 486.5k, beating estimates by ~5.3%.On Sep 30, Musk was appointed co-lead of the U.S. DoD 'Meridian Program', and SpaceX's cumulative DoD awards exceed $12.7bn.On Oct 3, Musk confirmed talks with TSMC on 'Terafab' (TSMC may own and operate the plant and provide advanced processes; Intel joined in Apr but progress has been limited).

4. Macro: Nonfarm payrolls missed.Fed officials turned more dovish, cooling Oct hike odds.

Dolphin Research's take: The market is pricing SpaceX's AI ARR as Anthropic‑like revenue, but it is not.This is bare‑metal compute leasing, priced at $30–45bn per GW, or 3–4x new cloud vendors.Each contract can be terminated by either party with 90 days' notice; $84.5bn is a cap, not backlog. Clients are paying a scarcity premium, which we expect to narrow as supply–demand balances by 2027–28.

Valuation:

Upside case — AI biz at approx. $1.2tn: ground compute leasing at ~$54bn ARR × 4.5 EV/ARR ≈ $245bn, space data centers at ~$814bn, plus Grok/X and other AI assets of ~$0.1–0.2tn.Rockets + Starlink at ~$1.4tn.Total ~$2.5–2.6tn ($190–195/sh), implying ~12–15% upside vs. $170. At $170, the implied valuation is ~$2.2–2.3tn, which sits in a neutral-to-optimistic fair range.

This upside cap effectively assumes high execution on Musk's space data center plan (100GW deployed brought forward to 2035 from 2045; Musk's own guide is around 2030).Delivery depends on three conditions — a step-change in launch costs, GPU radiation tolerance and vacuum thermal management, and sustained AI demand growth.

It is a 'probability‑weighted option', and each quarter's Starship reuse progress, launch cadence, and thermal validation will reset pricing.What is verifiable today: AI demand remains strong (rents are rising), and SpaceX, with a time‑to‑power edge (6–8x faster deployment, ~half the cost), has secured per‑contract pricing at 3–5x new cloud — with half the premium from scarcity and half from cancellable orders.Launch costs and thermal validation have yet to be delivered.

Cadence: unlocks are staggered — approx. 328mn shares each on Oct 9 and Oct 24 (historically, batches of similar size triggered ~4% brief pullbacks), with limited expected impact.The real test comes in the two trading days post‑Q3 print in early Nov, when ~1.3bn shares (28% of the 180‑day lock‑up pool, largest single batch) unlock.A further ~800mn shares come due on Dec 8.

Therefore, simply putting existing ARR online is not enough.The market needs new compute orders commensurate with capex to keep marking up ground compute leasing valuation.Otherwise, risk/reward above $2.6tn looks thin.

Supplement: Apollo is leading a $40bn debt raise to procure NVIDIA chips.Per FT, SpaceX plans ~$10bn in bank loans and ~$30bn in IG bonds (Apollo leading, Pimco in talks), targeting GPU delivery by 2027.Shares dipped ~1% after hours on the news.

The money itself is not new.Back in Aug, we flagged a financing 'bottomless pit': post‑IPO plus bonds, cash would be ~$100bn, 2026 capex ~$65bn, and a 10GW plan in 2027 could reach $240–280bn if fully built.At ~$35–40bn per GW, $40bn funds only ~1GW, about one‑tenth of the plan — the first ticket, not the full bill.

Choosing debt is the right call: it avoids incremental equity dilution amid unlocks.Securing an IG rating also shows credit markets view 'GPUs + blue‑chip contracts' as viable collateral.

Our concern is duration mismatch: multi‑year debt serviced by contracts cancellable on 90 days' notice, with chips as collateral that will date over a few product cycles.The 90‑day clause already leaves tech iteration risk with SpaceX, now layered with leverage.This is CoreWeave's playbook (pledge GPUs to borrow, then lease to majors), and the math hinges on pricing.

At current $30–45bn/GW rents, 1GW pays back in ~1 year.If rents fall to new cloud's $10–15bn, payback stretches to 3–4 years — near GPU life even before interest.

So this deal is a leveraged bet that scarcity premia persist.That is exactly what we think will fade: chips arrive in 2027, when premia start narrowing, making SpaceX's AI biz look like a levered new cloud strapped to a rocket.

We will watch three things: IG bond spreads (10Y UST ~5.2%, near 2002 highs), whether Starship Flight 15 achieves full two‑stage reuse via capture, and whether new leasing orders are signed before chips arrive.These will determine the sustainability of pricing and the path to de‑risking.

图片 1,共 1 张
D
Dolphin Research

MRVL: LT outlook soars - confidence or just hype?

Marvell hosted its Investor Day in New York last night (ET Oct 6, 2026), led by Chairman & CEO Matt Murphy and the executive team. This marked the first comprehensive update to its long-term outlook since the company postponed its 2025 Investor Day, and the first time it set targets for FY2031. Earlier, $Marvell Tech(MRVL.US) signed a new collaboration with Alphabet on custom ASICs, offering warrants to win orders; cf. 'Marvell: teaming with Alphabet with sweeteners — can it pry share from Broadcom?'

回 1M MARVELL 5408 十知T
Our growth continues to accelerate $20B 一 ◆ Total revenue 67% $20B $12B YoY $8.2
Custom revenue is accelerating Updated FY29 ) custom target FY29 custom target $
Segment What it does Representative products Key customers FY27 revenue (share) +2
MarvellHot topic
D
Dolphin Research

MRVL outlook ignites rally; SpaceX plans to borrow $40bn to bulk-buy NVDA | Daily News Recap

Oct 7 | Dolphin Research Focus: Macro/Industry — the 10Y UST yield hit 5.3%, the highest intraday level since 2002. European bonds sold off in tandem, with France at the center of the storm. Long-end yields pushed to new highs globally while the S&P 500 hovered near record highs, underscoring a sharp stock-bond divergence.

Ray Dalio warned the U.S. debt cycle is nearing its limit, with earnings (not multiple expansion) propping up equities for now. If rates keep rising, high-valuation tech would be first in the firing line. Single stocks — $Marvell Tech(MRVL.US) at its Investor Day...

图片 1,共 1 张
Today’s Key News Recap
D
Dolphin Research

When people think of AI's hardware appetite, the first thing that comes to mind is training. But the real squeeze on memory capacity is inference. Training does demand larger capacity — you need to keep intermediate states and activations, and run at BF16 or higher precision — so parameter memory can be 8–16x that of inference.

Even so, memory isn't a bottleneck during training: you can dedicate the whole compute cluster to a single model, leaving plenty of memory — like one person having an entire warehouse to themselves.

The crunch is inference. Clusters are partitioned into small slices, so each model instance may run on only dozens to a few hundred GPUs, making memory tight and I/O volumes grow with generation length. As a result, speed pressure concentrates on inference, which is why memory demand rises with app penetration and agent ramp — it's not lab training, but millions of daily user calls that truly burn memory.

图片 1,共 1 张
D
Dolphin Research

When memory runs short, most people assume the 'capacity' is the issue and just think about paying up for more. The real hurdle is bandwidth.

On the supply side: memory bandwidth has chronically lagged compute. From B100 to GB300 over five generations, bandwidth stayed stuck at 8 TB/s, while the bandwidth-to-compute ratio fell from 1.1 to 0.5 — meaning GPUs spend more time waiting for data.The new Rubin adopts HBM4, lifting total bandwidth to 22 TB/s, but compute also jumps 2–3x, leaving the ratio at only 0.6. The wall is still there.

On the demand side, the curve is steeper: inference read volume grows roughly with the square of output length. Each new token requires rereading activations and the entire prior cache. A 10x longer context drives ~100x more reads — for Qwen3.8 Max, generating another 100k tokens on a 100k context implies ~500 TB of reads.

Supply can’t catch up, while demand is expanding quadratically. Bandwidth is the toughest bottleneck in the memory stack.

图片 1,共 2 张
图片 2,共 2 张
D
Dolphin Research

Memory demand has a component that truly surges. It is the KV cache.

AI's need for memory seemed to spike 'overnight'. In reality, it breaks into two dimensions: more capacity and higher memory bandwidth.

First, capacity. It actually has two very different pieces: a fixed 'base load' and, more critically, an 'elastic' part that can blow up total memory.

The base load is model parameters, which scale nearly linearly and predictably, equal to parameter count times bytes per parameter. From the first-gen Qwen to Qwen3.8 Max, parameters rose from 72 bn to ~2.4 tn, and per-instance parameter memory from 135GB to ~2,300GB (~17x) — usage is straightforward.

Elasticity comes from KV cache during inference. It is non-linear, driven by context length and the compression efficiency of the attention architecture. Notably, Qwen3.8 Max's context is 8x Qwen2.5, yet per-session cache grew only ~12%, as software progress kept the per-session footprint in check.

You can cap a single session, but not the total. When users and sessions explode, aggregate cache across sessions can be tens to hundreds of times larger. That is why 'more users' drives memory demand more than 'bigger models'.

图片 1,共 3 张
图片 2,共 3 张
图片 3,共 3 张
D
Dolphin Research

AI can't rewrite the DNA — how long can SanDisk's rally last?

In two earlier pieces, 'From Leaves to Flowers: How AI Inference Can Revive NAND?' and 'NAND’s Prolific Nature: Why Can SanDisk Defend 80% GPM?', Dolphin Research argued that AI will not only lift NAND demand but could also break its long-standing 'silicon cycle' fate.

Under an inference-led paradigm, NAND is shifting from a peripheral data warehouse to an essential element on the compute path.

With the move from training to inference and longer context windows, today’s SSDs have effectively become a 'token battery' that stores compute...

a 2 1 三 c )SanDisk PROFESSIONAL
Figure 23: DRAM spot price trend Figure 24: NAND s D spot price trend W%2们 15.0
Sandisk ASP Unit: ($/GB) SNDK Flash $/EB assumptions ($/GB) V Y/Y 0 0.20 hinRese
Sandisk ASP Unit:($GB) SNDK Flash $/GB assumptions Y/Y 0.35 DolphinResearch Dolp+36
SandiskDeep Research
D
Dolphin Research

Zhipu GLM-5.3 goes global on AWS; GOOGL to invest $1bn in nuclear to bolster compute capacity|Daily News Recap

1006 | Dolphin Research Focus: 🐬 Macro/Industry. The Houthis claimed three waves of large-scale strikes on Saudi territory, targeting Riyadh's King Khalid Intl Airport and Aramco's Rabigh refinery.

Harassment along the Bab el-Mandeb strait has intensified, stoking concerns the conflict could shift from long-range strikes to physical control. Saudi Aramco's CEO warned global oil inventories are 'thin to a frightening degree', and even if hostilities ease, restocking could take two years.

Red Sea shipping insurance costs are rising, so the $100 oil risk remains. Middle East supply risk has picked up again. If Saudi core oil and gas facilities suffer material damage, oil prices would move up rapidly...

图片 1,共 1 张
Today’s Key News Recap
D
Dolphin Research

$Alphabet(GOOGL.US) $Alphabet - C(GOOG.US) Gemini 4 has finally rolled out, but for safety controls it is not yet open to individual users.It is limited to internal use and Gov. submissions for now, with phased access to consumers to follow.

Benchmark scores suggest Gemini 4 Argon is a major step-up vs. the prior gen, with overall intelligence now in the top tier and back among the AI Big Three.Pricing looks compelling as well (list price vs. Opus 5.5, but launched at a 50% discount), yet market reaction was muted, with shares giving back early gains intraday.

海豚君认为原因有三:They are as follows.

1. 可看不可用

Argon not being publicly accessible is the biggest bug.With leaderboard gaming increasingly common, hands-on tests by influencers have become the new gold standard, so company-disclosed benchmarks carry less weight when Argon cannot be independently tested.

2. 编程性能仍不领先

Gemini has long lagged in AI coding, so the market is focused on whether coding has improved.Argon leads GPT 6 Astra, Fable 5.1, and Opus 5.5 on DeepSWE (large-scale, multi-file feature implementation) and Vibe Code Bench (natural language to runnable full apps), but trails in frontier software capabilities (FrontierSWE v2), command-line ops (Terminal-Bench 4.0), and desktop system ops (OSWorld-2.0).In other words, it still falls short vs. OpenAI and Anthropic on long-running, hardcore coding tasks and native terminal workflows without a GUI.

3. 短期催化减少,但搜索侵蚀是长期持续

With the widely anticipated Gemini 4 catalyst now out, concerns around search erosion will resurface, and some near-term bulls may choose to take profits.Search erosion has always been an issue of timing and magnitude: while Google’s search volume share looks relatively stable, rising agent-driven search means volume/share no longer fully reflect shifts in revenue share.

与此同时 Meta Muse 承接了 Google 的一部分功能场景,也让资金加剧了对 Google 搜索的影响担忧,并期待 Google 能够推出同样的个人 Agent 来进行抗衡。Investors are looking for Google to release a comparable personal agent to counterbalance.

总体而言,近期的谷歌在 Gemini 4 相对 “不及预期”+AI 侵蚀搜索的空头叙事中而承压,再加上明年的利润削弱预期,情绪整体是偏消极的。A sentiment reset likely needs more catalysts to flip the narrative (e.g., Argon opening up, new agent launches), but the timeline remains unclear.

不过对于 Muse 等个人 agent 入口对 Google 的影响,正如我们此前对 Muse 商业化空间的分析,海豚君认为倒不必急于恐慌定价:Muse only launched about two weeks ago, with fast top-line traction so far at ~5 mn cumulative downloads and 700–800k DAUs; retention needs a full month of data.

与此同时,目前 Muse 最受欢迎场景是处理账单、取消无用订阅以及比价砍价等帮助个人财务省钱场景,以及整理邮箱、填表等个人生活杂务的处理,仍偏次抛的工具化属性,要拉时长做广告、购物等纯商业变现还是有点吃力。Its most popular use cases are bill management, canceling junk subscriptions, price comparison and bargaining to save on personal finances, plus inbox tidy-up and form-filling.It remains largely utilitarian with low stickiness, making it harder to drive time-on-app for ads or shopping monetization.

图片 1,共 5 张
图片 2,共 5 张
图片 3,共 5 张
图片 4,共 5 张+1
D
Dolphin Research

MU (Analyst huddle): SCA covers 35% of revenue; at least two nodes ahead of Chinese peers

Below is Dolphin Research's Trans of MU's FY26 Q4 post-earnings analyst call. For our earnings read-through, please see 'Micron: Without the melt-up, can long-term agreements really support a memory revival?'.

I. $Micron Tech(MU.US) Key Earnings Recap: 1) FQ1 modeling assumptions: guidance implies DRAM and NAND bit shipments up low single-digit QoQ, with unit costs showing double-digit change. 2) FY27 R&D raised: excluding incentive comp., ...

图片 1,共 1 张
MicronConference Minutes